PDF to Excel Without a Converter — Excel's From PDF, Why 00123 Becomes 123 (8 PDFs Tested)
Before uploading a PDF statement, roster or quote to a conversion site, try the converter already built into Excel: Data > Get Data > From File > From PDF. I tested 8 PDFs in Excel for Microsoft 365 — a Word invoice table with and without borders, a 60-row table spanning 3 pages with the header row repeated and not repeated, a Hangul 2024 PDF, a meeting-minutes PDF, a scan and a password-protected PDF — and recorded what came through as is and what changed.
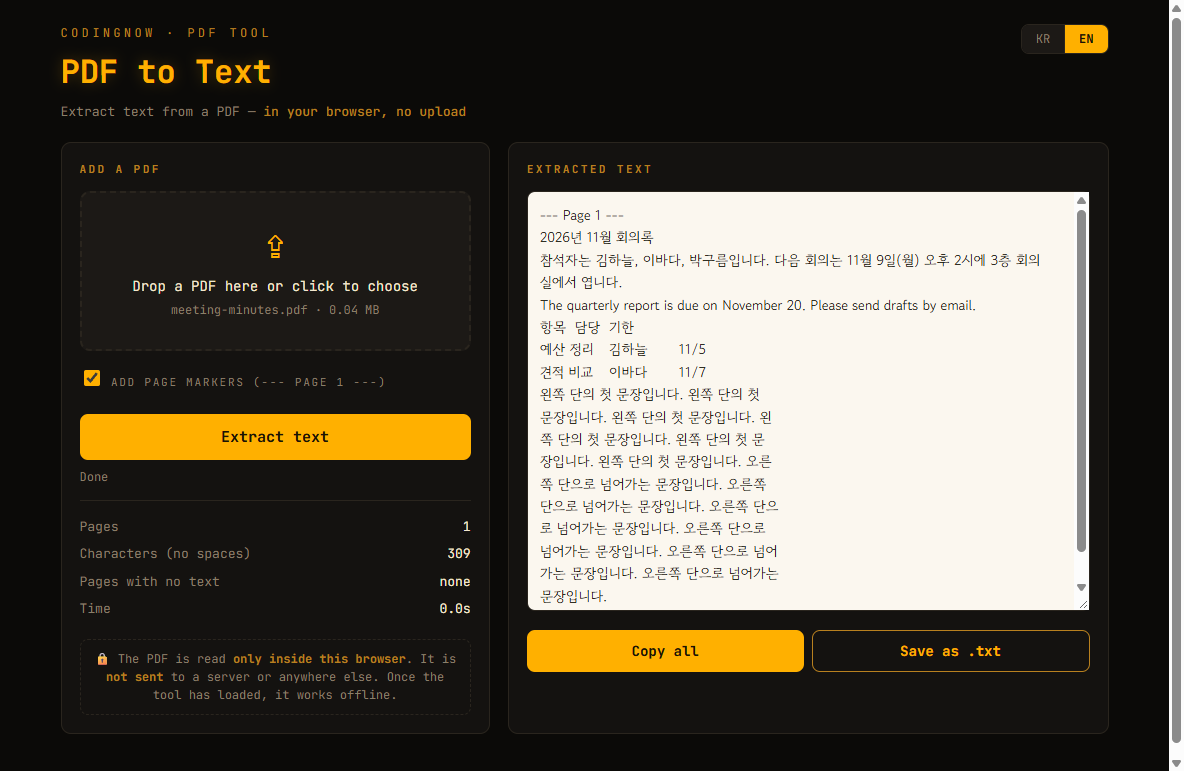
When Excel has no From PDF or a password PDF won't open — drop in the PDF and table cells come out tab-separated, so they split into columns when pasted into Excel. Enter the password if you know it. Nothing is uploaded.
- ✓ Free
- ✓ No install, no sign-up
- ✓ Runs in your browser
- ✓ Files are never uploaded
🔒 Your file is never sent to a server or anywhere else — it is processed only in your own browser.
Importing a PDF table into Excel — the menu path
- 1Open a new workbook in Excel and go to the Data tab.
- 2Choose Get Data → From File → From PDF and open the PDF.
- 3The Navigator lists tables such as 'Table001 (Page 1)' and pages such as 'Page001' on the left. Click a table to preview it on the right.
- 4Click Load to put it on a new sheet as a table, or Transform Data to fix things in the Power Query Editor first.
According to Microsoft's documentation, this is Power Query's PDF connector (Pdf.Tables), which returns the tables it finds in a PDF. Running the same function in a hidden Excel took 1.5–2.6 s per PDF to read the table list (Excel for Microsoft 365, version 16.0 build 20527).
| Test PDF | Tables in the Navigator | What came in |
|---|---|---|
| Word invoice table (borders, 5 rows × 5 columns) | Table001 (Page 1) | 5 × 5, intact |
| Same table, no borders | Table001 (Page 1) | 5 × 5, intact |
| 60-row table over 3 pages — header repeated | one Table001 (Page 1-3) | 60 rows (header once) |
| 60-row table over 3 pages — header not repeated | Table001 · 002 · 003 (one per page) | 22 + 24 + 14 rows |
| Hangul 2024 PDF (60-row table, 2 pages, header repeated) | Table001 · 002 (one per page) | 14 + 46 rows |
| Word meeting minutes (text, 3-column table, 2 columns) | Table001 (Page 1) | 3 × 3 table |
| Scan (the minutes as an image) | none — Page001 only | 0 tables |
| Password-protected PDF | didn't open | 'Pdf failed to load with result: Corrupted' |
The password PDF wasn't damaged, yet Excel reported 'Corrupted'. If you know the password, it was quicker to enter it in the PDF Text Extractor and paste the table.
The two automatic steps — why 00123 becomes 123
The Navigator preview already showed the item code as 123. After loading, the query's formula had two steps I never asked for.
Source = Pdf.Tables(File.Contents("…\invoice_border.pdf"), [Implementation="1.3"]),
Table001 = Source{[Id="Table001"]}[Data],
#"Promoted Headers" = Table.PromoteHeaders(Table001, [PromoteAllScalars=true]),
#"Changed Type" = Table.TransformColumnTypes(#"Promoted Headers",{{"Date", type date}, {"Client", type text}, {"Item code", Int64.Type}, {"Qty", Int64.Type}, {"Amount", Int64.Type}})
(My Excel runs in Korean, so the steps were named 승격된 헤더 and 변경된 유형 and the columns had Korean names; the code above is translated.) The table the PDF hands over is all text — columns Column1 to Column5, with 'Date, Client…' as the first row. Excel promoted that row to headers and then picked a type for each column from its values. Microsoft's documentation describes this automatic detection for unstructured sources such as Excel, CSV and text files, based on the first 200 rows; in this test it was applied to the PDF too.
| Value in the PDF | Value after import | Excel cell |
|---|---|---|
| 00123 (item code) | 123 | number, General |
| 01020 (item code) | 1020 | number, General |
| 1,250,000 (amount) | 1250000 | number, no comma format |
| 2026-11-02 (date) | 2026-11-02 | date (yyyy-mm-dd) |
| client name | unchanged | text |
Amounts turning into numbers is actually handy — you can total them right away. The problem is any column where leading zeros mean something: item codes, employee IDs, ZIP codes, phone numbers.
Keeping the zeros — edit the step, don't add one
- 1In the Navigator, click Transform Data instead of Load (if you already loaded it, double-click the query to open the editor).
- 2Under Applied Steps on the right, select Changed Type.
- 3In the formula bar, change
{"Item code", Int64.Type}to{"Item code", type text}(turn the formula bar on from the editor's View tab). - 4Click Close & Load.
I tried both on the same PDF. Adding a step after Changed Type that turns the item code into text gave '123', '456', '1020' — the zeros were already gone. Editing Changed Type itself kept '00123', '00456', '01020', and the amount (1250000) and date stayed a number and a date.
If there are too many columns to fix one by one, delete the Changed Type step. Every column stays text (1,250,000 included), and you set types only on the columns that need to be numbers.
When the table splits by page
Microsoft's documentation says similar tables on consecutive pages are combined into one automatically (on by default). The Word table with its header row repeated was indeed combined; without the repeat it split into three. The PDF made in Hangul 2024 had its header on page 2 as well, yet still split into two — I couldn't find out why it didn't count as 'similar'.
Split tables can be stacked again in Power Query. Combining the tables first and then promoting the first row gave exactly 60 rows for the no-repeat PDF.
Source = Pdf.Tables(File.Contents("…\long_norepeat.pdf"), [Implementation="1.3"]),
Combined = Table.Combine({Source{[Id="Table001"]}[Data], Source{[Id="Table002"]}[Data], Source{[Id="Table003"]}[Data]}),
Headers = Table.PromoteHeaders(Combined, [PromoteAllScalars=true])
Doing the same with a table whose header repeats on every page, like the Hangul 2024 PDF, gave 61 rows — one of them was page 2's header row left in as data. Filtering it out with Table.SelectRows(Headers, each [No] <> "No") (the first column's name) left 60.
Instead of From PDF — extract the text and paste
If your Excel has no From PDF, or a PDF won't open (like the password one), you can extract the table's text and paste it. The PDF Text Extractor put a tab between the cells of the same invoice table, so pasting into A1 split it into five columns (the borderless table came out the same).
| Pasted value | Excel cell (plain paste) | Column C formatted as Text first |
|---|---|---|
| 00123 | 123 | 00123 |
| 1,250,000 | 1,250,000 (number, comma format) | 1,250,000 (number, comma format) |
| 2026-11-02 | date | date |
Pasting also turned 00123 into a number. The amounts, though, came in as numbers with a comma format, so the total (5,857,733) worked straight away. For a column that needs its leading zeros, select it and set Format Cells → Text before pasting, and 00123 stays as is.
A scan gives 0 tables in From PDF and 0 characters in a text extractor, because it holds only images. Word does run text recognition (OCR) when you open one, but in the same meeting-minutes test it turned '3층' (3rd floor) into '3증', so check the result against the original.
FAQ
Q. Do I need to upload the PDF to a converter site?
If the PDF contains a table, try Excel's Data > Get Data > From File > From PDF first. In this test the table came straight into Excel with no upload step.
Q. After importing, 00123 turned into 123.
The automatic Changed Type step made that column a whole number. Select Changed Type under Applied Steps and change that column to type text. Adding a Text step after it leaves '123'.
Q. The table came in as one table per page.
Tables whose header row is only on page 1 split by page. Stack them with Table.Combine in Power Query, then promote the first row to headers. If each page had a header row, filter out the leftover header rows.
Q. Can it read password-protected PDFs?
Excel's From PDF gave 'Pdf failed to load with result: Corrupted' on the password PDF. If you know the password, enter it in the PDF Text Extractor and paste the table.
When Excel has no From PDF or a password PDF won't open — drop in the PDF and table cells come out tab-separated, so they split into columns when pasted into Excel. Enter the password if you know it. Nothing is uploaded.
- ✓ Free
- ✓ No install, no sign-up
- ✓ Runs in your browser
- ✓ Files are never uploaded
🔒 Your file is never sent to a server or anywhere else — it is processed only in your own browser.
Comments 0
No comments yet. Be the first.
Only members can comment.
Comments with ads, abuse, personal information or illegal content are hidden or removed. Members who post ads, spam, or hateful content are removed from the site, and everything they wrote is deleted. Comments are shown with your nickname. Privacy Policy